PRIME-RUNTIME
Scalable production intelligence
AI deployment platform
Intelligent runtime engine
Deploy. Scale. Optimize.
Deploy, scale, and monitor AI across cloud, edge, and hybrid.
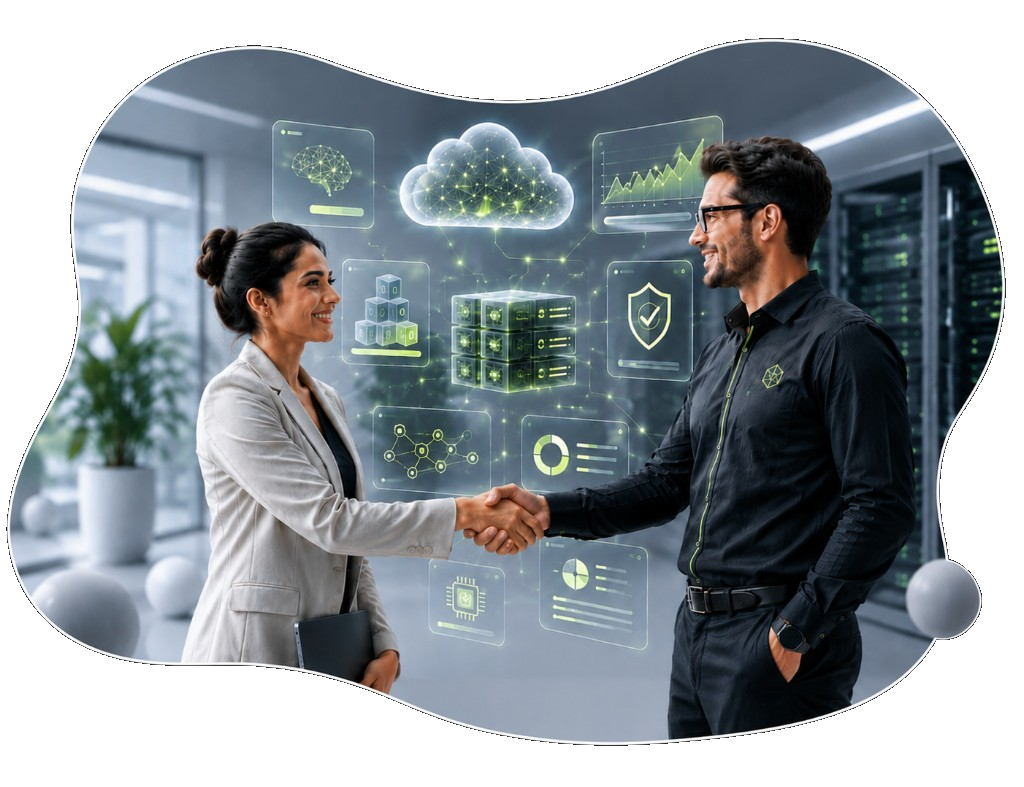
Run AI Without Complexity
Simplify production AI with automated deployment, intelligent scaling, and real-time runtime optimization from a single execution layer.
Platform at scale
The Execution Layer for
Production AI
PrimeRuntime sits between your models and infrastructure, automating deployment, optimizing inference, and scaling workloads in real time.
Three steps.
Live in production.
A linear deploy path from model artifact to scaled inference, no bespoke infra scripts required.

Connect your model
Upload your artifact or link from S3, Hugging Face, or your registry.
primeruntime connect --source
Configure runtime
Set compute, scaling rules, and routing for cloud, edge, or hybrid.
primeruntime config --runtime
Deploy to production
Launch with one click, monitoring and auto-scaling run from day one.
primeruntime deploy --productionCore Runtime
Everything you need to run AI in production, from deploy to observability.
- 01AI Runtime Engine
- 02Deployment Orchestration
- 03Inference Routing
- 04Auto-Scaling
- 05Runtime Dashboard
- 06Multi-Model Serving
- 07Cloud-Edge Deploy
- 08Performance Analytics
Plans designed for developers, teams, and enterprises deploying intelligent AI infrastructure
Subscription SaaS with usage-based inference billing.
Enterprise licensing available.
Runtime Core
For developers shipping their first production AI workloads.
- Up to 3 model deployments
- Cloud runtime execution
- Basic inference monitoring
- Auto-scaling (standard)
- API & SDK access
Runtime Pro
For teams running high-throughput inference at scale.
- Unlimited deployments
- Multi-model serving
- Advanced routing & load balancing
- Real-time observability dashboard
- GPU-optimized auto-scaling
- Priority support
Runtime Enterprise
For enterprises deploying intelligent AI infrastructure at scale.
- Dedicated runtime clusters
- Cloud, edge & hybrid deployment
- Custom SLAs & security controls
- Premium optimization modules
- Usage-based inference billing
- Dedicated solutions engineer
Trusted by AI Teams
MLOps engineers, DevOps teams, and enterprise IT running production inference.
"PrimeRuntime cut our inference latency in half and removed weeks of manual scaling work. Production deploys are now routine, not risky."

"We went from prototype to production inference in days. The runtime layer just works, routing, monitoring, and rollbacks included."

"Multi-model serving used to be a nightmare. PrimeRuntime handles routing and autoscaling so our team can focus on models, not infra."

"The observability dashboard gave us visibility we never had. Latency spikes are caught before customers feel them."

"Hybrid deployment was our blocker. PrimeRuntime unified cloud and edge under one runtime control plane."

"Usage-based billing aligned with our growth. We scale inference spend only when traffic scales. No wasted GPU hours."

Questions?
We've Got Answers
Common questions about deploying and running AI with PrimeRuntime.
Start Deploying Today
Tell us about your models and infrastructure. Our team will follow up with a tailored runtime plan.
- Response within 1 business day
- Enterprise deployment support
- Cloud, edge & hybrid workloads
Run AI in Production with Confidence
Deploy faster, scale smarter, and monitor everything from one runtime control plane.